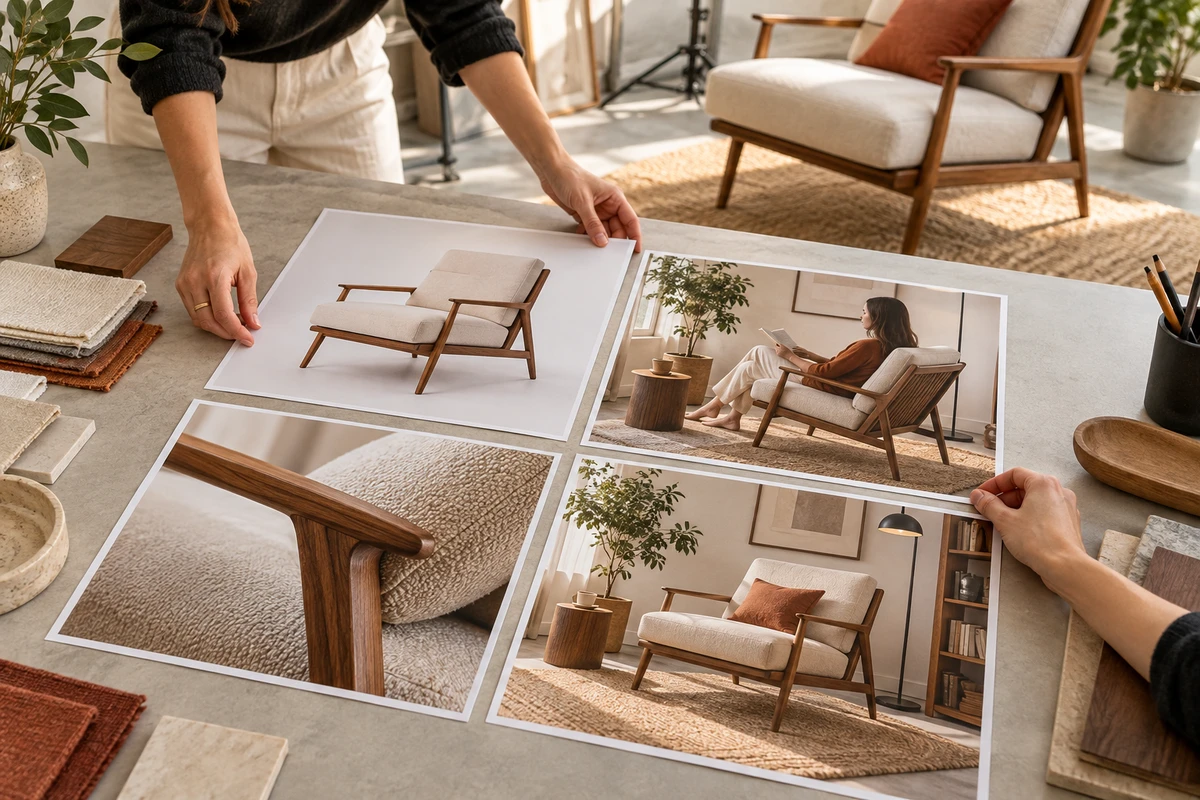
A shopper is using AI to picture a warm reading corner for a small apartment. A chair ad appears beside that process. The weak version merely looks polished. The risky version looks so much like the generated result—or the surrounding product interface—that the shopper could mistake sponsorship for part of the answer.
The useful version does a harder job. It remains unmistakably an ad while helping the shopper judge whether the chair fits the space, posture and constraints they already have in mind.
That is the procurement shift created by AI-native visual advertising. Brands do not just need another resized banner. They need scenes that can sit next to a live decision without pretending to be the decision engine.
The confirmed change is narrow, but strategically important
On October 5, 2026, OpenAI announced that it would begin testing a new visual ad format later that month in the United States with an initial group of advertisers. The first test is planned for image-generation moments on ChatGPT Free and Go. OpenAI says the ads will be clearly labeled, remain separate from the image being created and will not influence ChatGPT’s answers. This is an early test, not evidence of broad availability or universal performance. The announcement is explicit about that scope.
The surrounding advertiser documentation matters just as much as the format announcement. OpenAI says ad selection can consider the current conversation’s context and intent, along with the landing page, title, copy and advertiser-supplied context hints. Those hints describe what an offer is, who it helps and when it is useful. They are not exact-match keywords and do not guarantee delivery in a particular conversation. OpenAI’s guidance recommends specific, accurate phrases built around genuine use cases.
The creative implication is an ONCE analysis, not a platform promise: the unit of relevance is moving from a word to a situation. A visual must make sense beside a user’s current task, not merely contain the product category they mentioned.
Three jobs one generic product image cannot do
Prove identity
A clean catalog image can establish shape, color and model. That is valuable, but it rarely proves scale, handling, compatibility or outcome. If a portable grinder is shown without the hopper, grip, cup or beans that explain its use, the image may identify the object while doing little for the decision.
Explain fit
An image-generation prompt often contains useful constraints: a narrow counter, carry-on luggage, warm weather, one-handed operation or a particular design language. A generic lifestyle image may be attractive but too broad to show why the product belongs in that situation.
Preserve separation
The ad must be contextually close and visually distinct at the same time. OpenAI’s ad policies require ads to be distinguishable from the ChatGPT experience and allow removal or modification of ads that imitate its appearance, functionality or voice. The same policies require truthful claims and consistency across creative and destination.
That rules out a tempting shortcut: do not manufacture fake chat bubbles, generation progress, system controls or “AI answer” styling to borrow authority from the interface. Relevance should come from product usefulness, not from impersonation.
The ONCE Intent-Adjacent Scene Unit
Instead of commissioning one hero image plus crops, commission a four-frame scene unit. Each frame has a different decision job, and together they can support multiple headlines, context hints and placements without changing product truth.
Frame 1: recognition
Show the exact product clearly enough to distinguish model, material, color and important structure. Bind the frame to a SKU or offer ID. If the image depicts one model and the click opens another, the unit has failed before any performance metric arrives.
Frame 2: use
Show one real action that explains value: folding, fitting, pouring, cleaning, mounting, packing or operating with one hand. Avoid a vague “lifestyle” label. Name the action in the brief and make sure the product can perform it without editorial sleight of hand.
Frame 3: condition
Make the limiting condition visible. Scale can be shown with a hand or known object; compatibility can be shown at the relevant connector; capacity can be demonstrated with a truthful load. Some restrictions belong in copy rather than pixels, but the production team still needs to capture the visual information that makes them understandable.
Frame 4: outcome
Show the attainable end state: the packed carry-on, the completed pour-over or the reading corner with the chair in place. An outcome is not a fantasy render. If it depends on an accessory, professional installation, room size or a separate product, the destination must say so.
Every four-frame unit should ship with three records: one best-fit user situation, one non-negotiable limitation and one destination ID. This connects the scene to the context hint, copy and landing page instead of leaving media teams to reverse-engineer the meaning from filenames.
A four-question acceptance test
Use these questions before approving variants:
- Can the visual explain itself? Without the headline, can a reviewer still identify the product, action and differentiating detail?
- Is sponsorship unmistakable? Does any element imitate chat, generation status, controls or an assistant’s answer? The ad should not rely on the platform label to correct a misleading visual language.
- Can every implied claim be substantiated? Capacity, speed, compatibility and results must connect to product documentation or an appropriate test.
- Does the destination continue the same promise? The click should open the same SKU, situation and material conditions—not a homepage that forces the shopper to restart the decision.
OpenAI’s current creative guidance reinforces the practical direction: keep images simple and relevant, align the image with title and copy, create genuinely distinct variations, and link to the most relevant destination rather than defaulting to a generic homepage.
Price the usable situations, not the file count
For internal comparison, a brand can use this production lens:
Fully loaded cost per approved intent situation = (capture and generation assistance + retouching and adaptation + rights and claim review + destination adaptation) / scene units that pass all four acceptance questions.
This is not a market rate and it does not predict media performance. It exposes a common procurement error. Twenty near-identical crops may look like a large deliverable while covering one ambiguous situation. Eight genuinely different scene units, each tied to a truthful condition and a matching destination, may provide far more usable coverage.
This framework also stays separate from measurement. Our earlier guide to validating a ChatGPT Ads pilot covers signals, attribution and incrementality. The scene unit answers what to show for a situation. The measurement plan answers whether that choice changed a business decision.
Who should test first—and who should wait
A limited pilot makes sense when three conditions are present: the product’s value can be understood through a concrete action or spatial relationship; distinct situations genuinely need distinct images; and the destination can resolve to the correct SKU, terms and availability.
Fix the foundation first when the product relies on tightly regulated claims, every ad leads to a generic homepage, US usage rights are unclear, or AI-assisted imagery cannot preserve product detail. An early format is not a reason to relax factual or rights review.
Our forecast is that AI-native ad systems will ask for more context-rich variations and stronger connections between creative and destination. That forecast is not a confirmed product roadmap. The actionable fact today is simpler: a brand should stop treating one polished hero image as universal. Build visual scenes that are useful beside a live intent, obviously sponsored, factually supportable and continuous with the page after the click.
Sources
- OpenAI, “Building advertising for the way people use AI,” October 5, 2026.
- OpenAI Help Center, “Ads in ChatGPT: The Basics,”“Write Context Hints for ChatGPT Ads,” and “Create Ads for ChatGPT Ads.”
- OpenAI, “Ad policies,” updated September 10, 2026.
- U.S. Federal Trade Commission, “Native Advertising: A Guide for Businesses,” used for the general principle that sponsorship disclosures should be clear, prominent and close to the advertising message.