Social Short-Form Video Marketing Research 10/10
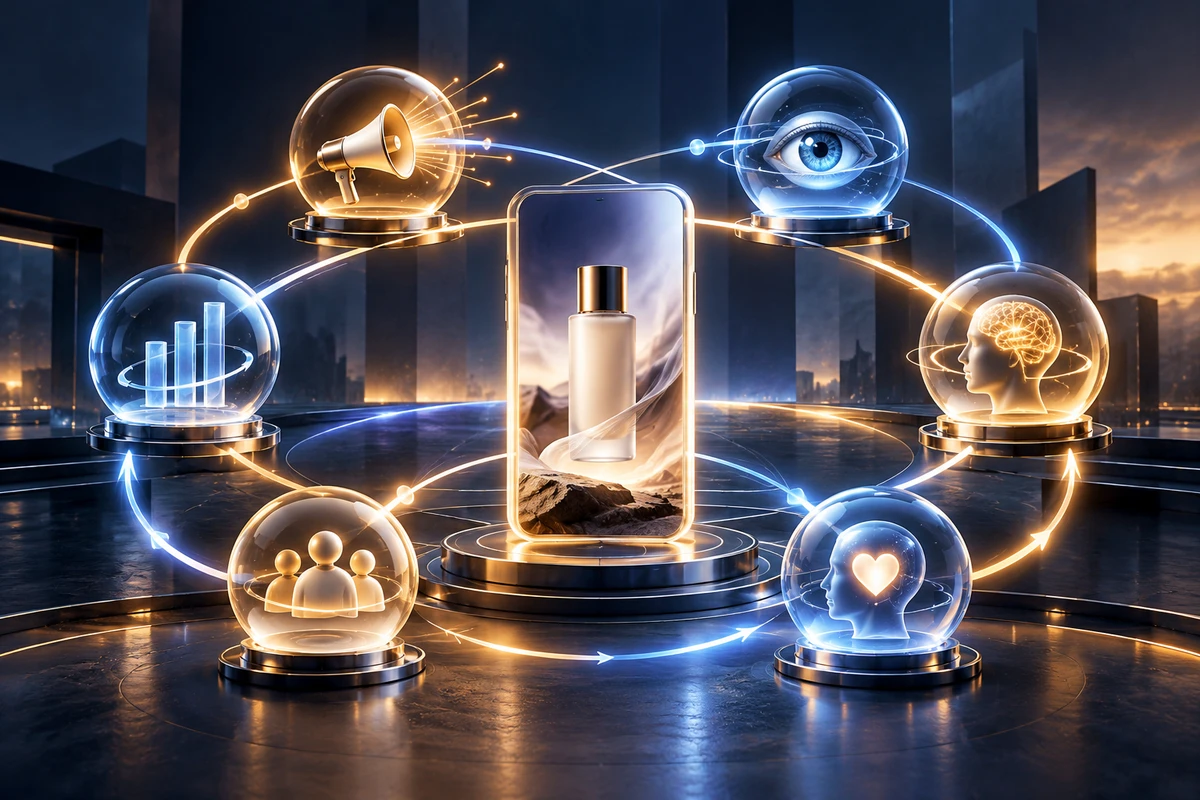
Short-form video marketing is not a straight funnel from exposure to viewing to purchase. A more accurate model is a conditional system formed by platform distribution, audience processing, product persuasion, brand memory, social transmission, and cross-platform decisions. Any condition can amplify what came before it—or cut it off. High reach does not guarantee understanding. High retention does not mean the product became a reason to buy. Strong emotion may leave behind the story while losing the brand.
This final article synthesizes the previous nine studies into ONCE's Six Conditions and Four Feedback Loops framework. It is not a universally validated theory or a formula for platform algorithms. It is a set of working hypotheses that can guide creative decisions, measurement design, and falsifiable tests. Research was checked through October 5, 2026, with emphasis on primary research and official platform material from 2025–2026. Results from different countries, platforms, industries, and ad formats are not treated as interchangeable.
Why the same good video can produce different outcomes
The claim that good content naturally finds its audience collapses at least six questions into one: who had a chance to see it; who chose to stop; who understood it; who believed the product claim; who remembered the brand; and who later searched, compared, shared, or bought. Platforms optimize user experience, engagement, or long-run satisfaction. Brands care about comprehension, memory, and incremental outcomes. Those objectives can overlap, but they can also conflict.
YouTube's official Shorts search and discovery guidance says that viewing choice, average view duration, average percentage viewed, likes, and post-watch surveys can inform ranking, alongside personalization and viewing history. It does not reveal internal weights or show that any one signal guarantees a brand outcome. Jeremy Yang, Juanjuan Zhang, and Yuhan Zhang likewise distinguish product-related effective engagement from engagement that may be driven by something else in their 2025 study of influencer video advertising. Their work does not make every TikTok market, or today's Douyin, the same environment.
Short-form video therefore should not be assessed with one total score. The first question is which condition a piece of content satisfies—and which condition stops working.
The six conditions
1. Opportunity: did the right people receive a viewing opportunity?
Exposure is not an inherent property of content. It emerges from recommendation, bidding, account relationships, user history, timing, and viewer choice. Two assets can have identical reach while facing completely different audience compositions. The first study in this series examined how recommendation systems shape who sees a Short. For a brand, the first diagnosis is not why a video failed to go viral. It is whether exposure came from people, contexts, and entry points that matched the task.
This creates the first competition: the platform may find people most likely to interact, while the brand needs people most likely to understand or buy. Optimization is efficient when those groups overlap. When they diverge, stronger platform performance can conceal a larger audience shift.
2. Processing: did stopping, continuing, and understanding occur together?
Attention is necessary but insufficient. Sammy Wals and colleagues studied 2,520 viewing experiences across 42 public-service announcements in research published in 2026. Shorter scenes and lower visual complexity were associated with greater attentional synchrony, and responses to cuts were delayed. The study concerns public-service ads, eye-tracking synchrony, liking, and recognition—not real purchases in a shopping feed. That boundary matters: faster cutting may increase momentary attention while reducing the time available to understand a product action, condition, or result.
The second competition is therefore between continuous stimulation and diagnostic information. One helps retain the gaze; the other helps viewers understand why the product matters. A useful creative comparison should observe early viewing choice, arrival at the key scene, product-related attention, and comprehension, rather than allowing completion rate to decide alone.
3. Persuasion: does the product have a non-substitutable causal role?
Entertainment can make someone finish a story. A purchase reason requires the product to connect a problem to an outcome. For low-involvement, low-risk categories, familiarity, emotion, and social cues may be enough to prompt the next step. High-ticket, high-risk, or technical products need more verifiable demonstration, conditions, evidence, and source credibility. If the reversal still works after the product is removed, it is more likely to be remembered as content than as product persuasion.
This does not mean every video should resemble a manual. It means the product needs a story job: whose situation it changes, through which action, and under what limits. In production, ONCE's short-form video solution organizes the opening, product action, proof shot, and variable versions within one shoot plan. It is a production method, not research evidence or a promise of performance.
4. Ownership: can viewers return the memory to the brand?
Branding is not simply better when it appears earlier or larger. It has to appear while meaning is being formed. Name, product form, color, sound, people, and usage context can become retrieval cues, but novelty can compete with the brand for memory. Early branding can establish ownership or be ignored before viewers understand. An end card may be complete but invisible to people who left earlier.
Brand linkage should therefore be measured separately: content recognition, aided recognition, unaided recall, and brand retrieval in a buying situation are not the same outcome. Immediate reach is not long-term brand equity. Tests should also check whether a series preserves stable assets instead of making every video novel enough to resemble a different brand.
5. Transfer: can influence continue outside the current player?
People may not click. They may save, verify in comments, send the video to a colleague, search the brand, or compare it on retail and offline channels. In a 2025 large-scale randomized field experiment on ByteDance, Yitian Liang and colleagues found that a substantial share of measured advertising effects for an automobile brand occurred beyond the platform. The result is an important measurement warning, but it belongs to a specific brand, platform, period, and experimental design. Its multipliers do not apply to every industry, and paid-ad spillover is not the same as organic word of mouth.
Low-risk products can more readily complete an action within a short path. High-risk or high-ticket decisions are more likely to generate delayed search and cross-platform validation. Share count without an exposure denominator cannot distinguish stronger motivation to share from simply receiving more exposure. Social diffusion and cross-entry decision making need their own condition rather than being treated as synonyms for the end of a funnel.
6. Learning: was the observed change really caused by the content?
Attribution asks which touchpoint receives credit. Incrementality asks whether the outcome would have happened without the intervention. Randomized holdouts, geographic experiments, quasi-experiments, and platform attribution observe different counterfactuals. Recommendation systems also redistribute exposure dynamically, so assets gradually face different audiences. Comparing conversion rates can turn selection bias into a creative verdict.
Jennifer Brennan and colleagues' WWW 2025 research on symbiosis bias shows that recommendation algorithms sharing training data can influence one another and violate the no-hidden-treatments assumption. The object is recommendation-algorithm testing, not a brand creative test. The transferable lesson is narrower: experimental groups in a dynamic system may not be truly isolated. The eighth article in this series develops the full measurement division between attribution and incrementality.
The four feedback loops
The opportunity loop connects distribution and early feedback. Viewing choice, retention, and negative feedback affect later exposure; later exposure changes the composition of the sample. Creative metrics are both outcomes and inputs to the next round of distribution.
The meaning loop connects attention, understanding, product causality, and brand ownership. A cut can refocus attention, but a diagnostic product action needs time. A story can increase immersion, but the product must do causal work. Brand assets need repetition without interrupting comprehension. There is no universal pace—only an allocation that is more suitable for a particular task.
The transfer loop connects sharing, search, comments, and off-platform decisions. A problem-solving video may look quiet in public engagement while performing a role in private forwarding or later search. A controversial video may generate many comments while eroding trust. They cannot be judged by one engagement rate.
The learning loop connects measurement to the next creative cycle. Generative AI can multiply supply, but Remi Daviet and Yohei Nishimura's 2026 image-ad study frames the challenge as both search and brand alignment, using active learning to optimize performance and acceptability. It studies image ads and click-through rates, not proof that AI video outperforms people. If every new version simultaneously changes the creator, opening, proof, brand asset, and call to action, more output produces less interpretable learning.
Turn conflicts into a creative portfolio
The practical conclusion is not to create one video that does all six jobs. It is to build a portfolio with distinct responsibilities. A hero brand film can carry a world, emotion, and distinctive assets. Product shorts can carry actions and evidence. Creator content can carry experience or expertise. Search-oriented explainers can answer comparison questions. Paid versions can provide controlled reach and clearer variables. Organic distribution, creator partnerships, and paid media can cooperate, but their source and objective should be recorded separately.
ONCE's public Oraimo dual-electric fat-bike coastal short-form case illustrates content organization: the page describes how terrain, tires, frame, and riding actions connect product and setting, while explicitly avoiding claims about speed, range, or safety. This is an observation about published organization, not evidence of sales, traffic, or brand lift.
Before production, write one row for every version: target audience, opportunity source, one thing to understand, the product's causal job, stable brand cue, expected next step, primary metric, and counter-metric. Counter-metrics are essential. When early retention rises, does comprehension fall? When creator closeness rises, does technical credibility fall? When version count expands, does brand recognition dilute?
Eight falsifiable predictions
- Assets with equal aggregate retention but different audience composition will produce different comprehension and incremental outcomes.
- When more frequent cuts reduce the duration of diagnostic shots, early attention may rise while product understanding falls.
- In high-involvement categories, emotion is more likely to prompt a next step when the product plays a causal role and verifiable evidence is present.
- Experience claims will depend more on creator closeness, while technical or high-risk claims will depend more on expertise; disclosure will alter the trade-off.
- Share counts will predict diffusion only when interpreted with exposure denominators and sharing paths; private sharing will be under-observed.
- High-risk and high-ticket decisions will more often create delayed search and cross-platform verification than immediate in-platform conversion.
- Automatic allocation can improve short-run delivery efficiency while reducing causal comparability between creatives.
- More AI variants will reduce interpretability when each variant changes several creative dimensions at once.
These are predictions, not reported results. They can be tested by stratifying audience and entry point, holding one variable stable, using a holdout where feasible, and defining sequential decision rules in advance. Failure is informative. If brand linkage does not affect later search, or a clearer demonstration does not affect understanding, the team should revisit the category, sample, measurement timing, and competing explanation.
A minimum test
A low-cost minimum test can compare two versions while holding the creator, length, media entry point, and call to action constant. Version A opens with emotional conflict and then demonstrates the product. Version B begins with a diagnostic product action and then enters the emotional setting. Predefine three levels of outcomes: opportunity-level viewing choice; processing-level arrival at the key scene and product comprehension; and action-level brand search, qualified click, or incremental behavior in a holdout. Measure brand recall separately rather than substituting reach.
If the platform dynamically tilts delivery, record audience and time for each version and use controlled media, geography, or audience holdouts when possible. Do not turn noise into a winner when samples are insufficient. If results are checked repeatedly, predefine stopping rules rather than ending at the first favorable fluctuation. This is an experimental proposal, still to be validated, and it does not replace a full causal design.
Conclusion: manage a learnable system, not a universal video
The ten studies converge on one judgment: short-form video outcomes are not determined by a single hook, completion rate, creator, brand reveal, or number of AI variants. They depend on whether six conditions support one another for a specific audience, platform, category, and decision stage. The real management task is the connection between opportunity, processing, persuasion, ownership, transfer, and learning.
The framework can easily become another checklist. A better use is to expose conflict: which metric hides another loss; which platform feedback pulls content toward the wrong audience; which brand requirement interrupts product understanding; and which apparent winner simply received a different audience. When teams can ask those questions, production starts accumulating knowledge instead of merely accumulating assets.
If you are planning always-on social content, paid creative, and product-proof versions, start with ONCE's short-form video production and versioning approach and turn the six conditions into a portfolio that can be shot, tested, and reviewed.
Sources and limits
Core sources checked for this article include YouTube Help, “Search & discovery tips — Shorts” (checked October 5, 2026); Yang, Zhang, and Zhang, “Engagement That Sells: Influencer Video Advertising on TikTok,” Marketing Science 44(2), online first December 20, 2024; Liang et al., “Is the Money Spent on Short-Form Video Social Platforms Worth It?,” Marketing Science 44(5), 2025; Wals et al., “The dynamic effects of visual complexity and scene cuts on viewer attention,” Journal of the Academy of Marketing Science 54, 2026; Brennan et al., “Reducing Symbiosis Bias through Better A/B Tests of Recommendation Algorithms,” WWW 2025; and Daviet and Nishimura, “Leveraging Generative Artificial Intelligence to Create Visual Content in Digital Advertising,” published online May 5, 2026. Study contexts and transfer limits are stated beside the relevant claims. We did not conduct a meta-analysis, replicate the studies, or claim that this framework has already been validated across platforms.