The answer should not be “whichever record is newest,” and it should not be “a person will review the final output.” Before a business agent connects to commerce, design, social, advertising and finance systems, a brand needs to decide which source is authoritative for each critical field, where that answer applies, when it expires, what evidence supports it and who resolves a conflict.
Without those rules, more connectors can create a more convincing mistake.
On September 29, 2026, Meta announced Muse for Small Business. Meta says the product can connect tools including Shopify, Canva, Figma, QuickBooks, Klaviyo, Stripe and Slack, as well as Facebook and Instagram business accounts. It can analyse sales, campaigns and social activity, then draft a plan or campaign. Meta also says nothing publishes, sends or spends without the user’s approval.
Those are documented product capabilities and control commitments. They do not establish that information across connected systems is automatically consistent. They also do not prove that the wider marketing industry has solved context governance. The operational question is harder: when the source systems disagree, is the approver seeing the correct fact, or merely a polished output built on the wrong one?
Approval is a control point, not a truth engine
Consider a hypothetical US launch for a product made in China. Shopify lists the current price at $79. An old Canva launch deck still says $69. The Figma master visual promises “up to 20 hours,” while the latest engineering record for the production SKU says 18. Instagram comments keep asking whether the device lasts 20 hours.
None of those records must be fraudulent. They may belong to different versions, time windows or purposes. If an agent treats the most frequently repeated claim as truth, customer questions can be mistaken for a specification. If it always selects the most recently edited file, a temporary campaign asset can overwrite an evergreen product fact.
By the time a human reviews the draft, the output may look coherent: the tone is on-brand, the logo is correct and the call to action works. A reviewer may not know which upstream specification the agent selected. Final approval can stop an action, but it cannot automatically repair a bad factual choice that has already shaped the script, visual and offer.
The problem is becoming material. A World Federation of Advertisers survey, published on September 30, found that 96% of respondents use generative or agentic AI in marketing and 46% use workflow automation or autonomous agents. Seventy-five per cent require human oversight. The sample was 54 senior respondents at 46 major brand owners, so it is evidence of governance direction among large advertisers, not an industry-wide average for every company.
Adobe’s 2026 AI and Digital Trends research surveyed 3,000 executives and practitioners. Seventy-five per cent cited data integration and quality as the top challenge to implementing agentic AI, while only 39% reported a shared customer data platform capable of supporting agentic AI. Connecting systems and making their answers reconcilable are different jobs.
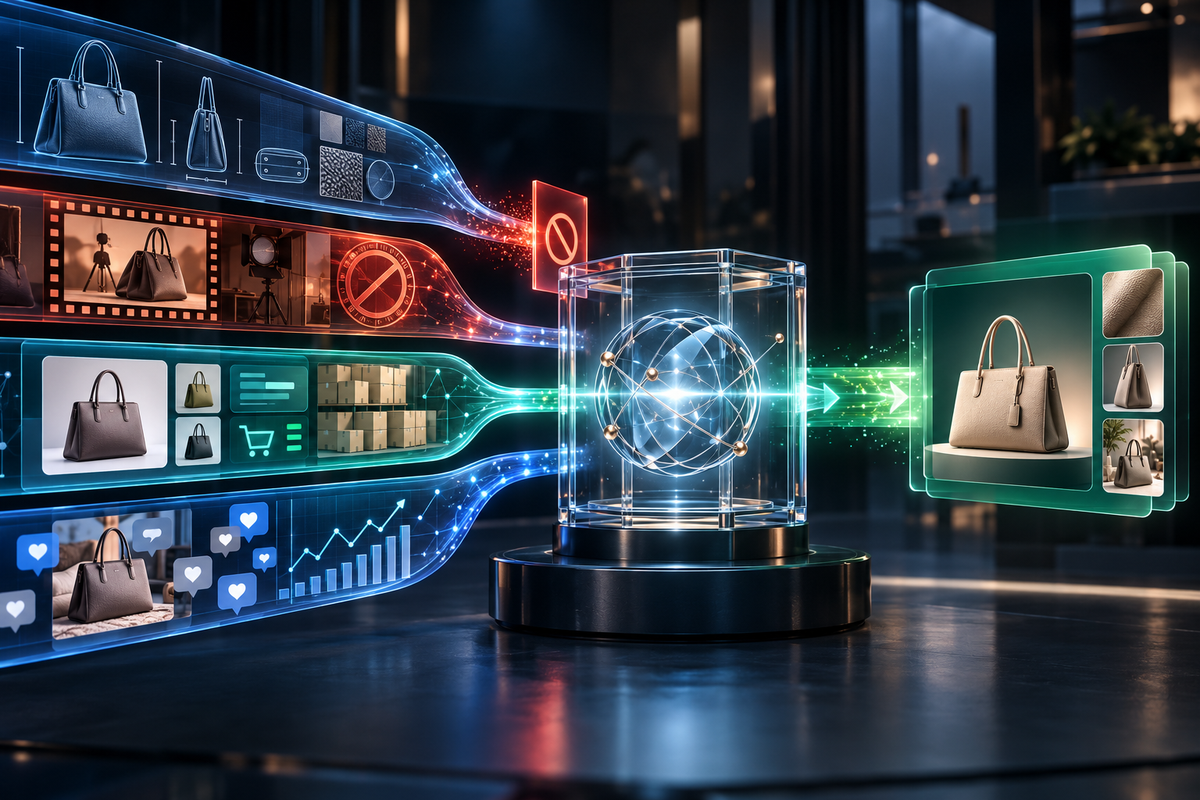
Four clocks for four kinds of brand context
ONCE recommends separating the information an agent can read into four clocks. Each clock should have its own authority, expiry rule and accountable owner.
The Product Clock
This covers specifications, materials, dimensions, performance, packaging and regulated claims. It usually changes with a SKU, hardware revision or legal requirement. The current engineering, quality or legal record should outrank an old sales page, design file or customer comment. A campaign cannot rewrite the product.
The Rights Clock
This covers talent, music, fonts, creator content, territories and usage terms. A file can remain in storage after its licence has expired. Even if the old creative performed well, an agent should block, replace or escalate an asset that no longer has valid rights.
The Campaign Clock
This covers price, inventory, offer, channel, market and start/end dates. It changes quickly and should expire automatically. A $69 US launch offer may be valid for one week without being valid for Europe, the evergreen product page or another SKU.
The Learning Clock
This covers clicks, views, comments, search terms and creative hypotheses. These are probabilistic signals, not product truth. Repeated “Does it last 20 hours?” comments reveal a customer concern; they do not change an 18-hour specification. Learning can propose a test. It should not overwrite facts or rights.
The ONCE Context Arbitration Board
Do not begin with a huge knowledge-base project. Start with 20 to 30 fields where a wrong answer could create a meaningful cost. For each field, record five things:
- Authority: the person or system allowed to confirm the field, not simply store it.
- Scope: the SKU, market, channel, language and audience to which the answer applies.
- Clock: Product, Rights, Campaign or Learning, including update and expiry conditions.
- Evidence: the engineering record, contract, campaign order, approval or test behind the answer.
- Conflict Route: whether the agent may select a version, must pause, or must escalate to product, legal, marketing or commerce.
Automatic resolution should be narrow: the same authority, the same scope, a clear version relationship and an unexpired replacement. If the authorities differ, the scopes differ, an expiry is missing, or a learning signal attempts to overwrite a product or rights fact, the agent should stop instead of guessing.
This principle is consistent with the NIST AI Risk Management Framework Playbook, which recommends monitoring external inputs and third-party resources, maintaining clear lines of responsibility, tracking exceptions and escalations, and documenting go/no-go decisions. NIST is not a marketing-specific rulebook. It is useful here as a governance foundation: errors should be detectable, decisions traceable and unsafe actions stoppable.
A 30-day pilot should test stopping, not copywriting
Choose one priority SKU, one market and one content workflow—for example, US product video and paid-social adaptations. In weeks one and two, map the critical fields and four clocks. In week three, deliberately inject conflicts: an old price, an expired talent licence, two specification versions, a promotion from another market and an unverified claim from social comments. In week four, review four measures:
- How many real conflicts did the agent detect?
- How many did it incorrectly resolve on its own?
- How long did an accountable owner take to adjudicate a pause?
- Which errors still entered a script, visual or publishing queue?
The objective is not to prove that a model is clever. It is to locate the automation boundary the brand can afford. Clear-version, reversible work can move faster. Conflicts involving product claims, asset rights and actual spend need named human responsibility.
For brands that manufacture in China and sell internationally, this architecture has a practical advantage. Engineering evidence, sample changes, real product footage and local-market messaging can sit on one traceable chain. A production partner’s job is no longer only to deliver a finished film. It is also to connect every important claim to the correct product version and create footage that future agents can safely call, while international teams adapt the expression for market and channel. ONCE’s global launch content model is built around that division of work: evidence and production close to the supply chain, adaptation close to the audience.
Before asking how many applications a business agent can connect, ask a stricter question: when four systems all provide an answer, does the agent know which one is not authorised to decide?