Imagine typing: “Launch a US acquisition campaign for the new product. Use video and display. Cap spend at $50,000.” Minutes later, the system has divided the budget, selected audiences, generated assets and prepared the campaign for launch. The risk is not that the agent worked quickly. It is that “help me plan” quietly became “act on my behalf.”
The practical answer is simple: without spend limits, an action whitelist, named approvers, decision logs and a tested stop-and-rollback path, an advertising agent should be allowed to read, recommend or draft—but not execute. The product a brand is buying is no longer just automation. It is a set of decision rights that must be executable, auditable and revocable.
The shift is from recommendations to account actions
On October 5, 2026, TikTok said its TikTok for Business MCP lets developers build agents and tools that can plan, launch and manage advertising workflows. The company also listed connectors across several AI platforms and the IAB Tech Lab Agent Registry. That announcement establishes TikTok’s product direction and available connection path; it does not prove that every advertiser, market or agency has adopted agentic buying.
Amazon Ads made the operating model more tangible in its September 29 DVA+ announcement. Advertisers choose an objective, products or a brand URL, review AI-generated creative, set a budget and launch. The system can handle targeting, inventory selection, format allocation, bidding, creative generation and ongoing optimization, while advanced settings retain manual controls. At publication, however, Amazon described DVA+ as an extended closed beta in the United States, with an open beta expected in late October and broader expansion still targeted for later dates.
The transaction layer is moving too. IAB Tech Lab’s September 22 AAMP 3.0 release introduced OpenProposal, a specification intended to make the RFP-to-buy process readable by buyer and seller agents. It connects discovery, proposal comparison, negotiation, buying, execution and reporting, but the specification remains in public comment through October 22, 2026. IAB Tech Lab’s buyer-agent reference documentation also keeps a human approval gate before spend is committed and records quotes, negotiations, allocations and bookings as structured events.
The confirmed signal is therefore not “media buying is now autonomous.” It is that multiple layers of the stack can now carry an agent from a brief toward a real transaction. ONCE’s inference is that brands must design permissions before they optimize for automation.
The ONCE five-level authority stack
Avoid governing agents with a single “AI on” switch. Assign authority action by action:
| Level | What the agent may do | What the brand must specify | Sensible default |
|---|---|---|---|
| Read | Access accounts, products, inventory, results and approved assets | Data scope, retention, tenant separation, sensitive fields | Start read-only |
| Recommend | Suggest audiences, budgets, placements, creative and tests | Objectives, evidence threshold, excluded markets, prohibited inferences | Human acceptance required |
| Draft | Build paused campaigns, generate assets, fill tracking fields | Templates, naming, rights status, prohibited claims, QA rules | Write drafts, not spend |
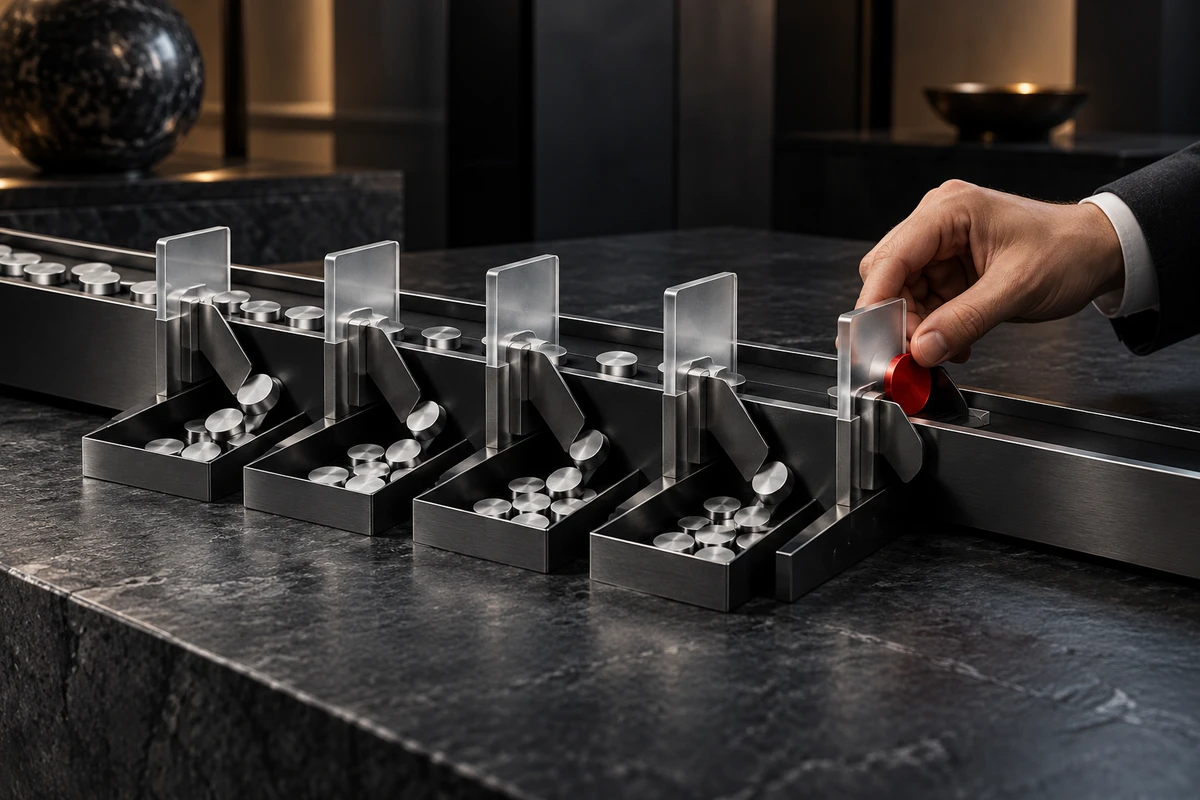
| Execute | Launch, bid, reallocate budget, replace assets, add placements | Per-action and cumulative caps, field whitelist, approval thresholds, hours | Allow only inside a bounded envelope |
| Stop and recover | Pause anomalies, revert to an approved state, restore service | Triggers, on-call owner, recovery approval, evidence retention | Automate stopping before recovery |
This is not a maturity ladder. An agent may be allowed to pause spend but forbidden to increase it. It may generate twenty paused campaigns while a person selects the three that go live. Authority should follow the reversibility of an action, not the product label attached to the agent.
An agent charter needs more than a media brief
A conventional brief names the audience, objective, market, timing and KPI. An agent that can write to an ad account needs a one-page operating charter with at least nine additional decisions:
- Accounts and markets: which accounts, stores, countries and objectives are readable or writable.
- Allowed actions: whether the agent may draft, launch, pause, change bids, move budget, widen placements or replace creative.
- Spend limits: per action, per day, per campaign and per account, plus escalation thresholds.
- Field whitelist: editable and locked fields, including destination URLs, pixels, attribution windows and brand-safety settings.
- Creative and claims: approved asset pools, rights windows, prohibited language, regulated claims and generated content requiring review.
- Data conditions: which conversion, margin, inventory and return signals may guide optimization, including fallback behavior when data is delayed.
- Approval ownership: who signs off on first launch, budget increases, new markets, new audiences, new creative and recovery.
- Logging: timestamp, initiator, input, before-and-after values, reason, approver and linked version for each action.
- Stop and rollback: pause triggers, recoverable state, response time, incident owner and restart conditions.
If a team cannot fit these decisions on one page, it is not ready to grant execution authority. Keep the agent in recommendation and draft mode until ownership is clear.
When to use a copilot—and when bounded execution is reasonable
Stay in copilot mode
Keep the agent at read, recommendation and draft levels for a first market launch, regulated or efficacy claims, volatile pricing or inventory, sparse conversion data, unresolved cross-team ownership, or fragmented creative rights.
Generative creative makes this especially important. An agent may see a product page without seeing talent consent, music territory restrictions, creator authorization windows or the brand’s prohibited claims. A generated asset is not automatically a deployable asset. The related ONCE guide to an AI creative asset passport explains how provenance, rights and approval records should travel with the file.
Permit bounded execution
Bounded execution becomes reasonable for stable products, reliable landing pages and conversion events, explicit margin or inventory signals, repeatable campaign patterns, fixed naming and tracking conventions, and teams that can enforce real-time caps, action logs, automatic pause and human recovery.
Begin with reversible actions: create paused drafts, complete approved templates and pause when a rule is breached. Then graduate to limited bid changes, budget moves and asset replacement. Keep first launch, new countries, material budget increases, core claim changes and post-incident recovery behind a human gate.
This is why activation-ready creative delivery becomes an operational prerequisite. An agent can execute safely only when it receives approved versions, channel mappings, tracking identities and rights status. Otherwise, automation merely accelerates ambiguity.
Measure cost per auditable decision, not hours saved
When comparing manual buying, copilots and bounded execution, calculate the fully loaded cost per auditable decision:
Cost per auditable decision = (platform and model fees + integration maintenance + human approval + logging and audit + rework and rollback + expected incident response) ÷ reconstructable valid decisions
A valid decision is not an API call or a prompt. It is a business action with a known result: a budget move within limits, an anomaly pause, an expired asset replacement or a rejected recommendation. The record must answer who initiated it, what evidence was used, what changed, who approved it and what happened next.
This denominator reveals what an “hours saved” estimate misses. An agent may reduce trafficking time while increasing review, explanation and incident work. And an optimization that cannot be reconstructed does not become a reusable decision asset, even if short-term performance looks positive. ONCE’s guide to why a winning ad still needs causal discipline is the next layer once clean decision records exist.
Test obedience before optimization
Do not make ROAS uplift the only acceptance test. Start with a stable product, limited budget and clear rights. Run the agent in a sandbox or against paused drafts and verify four things: it reads only permitted data, changes only whitelisted fields, stops at approval gates and produces a complete action history. Then permit a small amount of live spend with automatic pause. Recovery, market expansion and large budget changes should remain human-controlled.
NIST’s AI Risk Management Framework calls for human-oversight processes to be defined, assessed and documented. Its playbook also recommends histories, audit logs, override records and explicit go/no-go accountability. That framework is not an advertising-platform rule, but it provides a useful cross-platform procurement baseline: a human must have more than ceremonial approval. A human needs the power to see, stop and reverse.
The durable advantage of advertising agents will not be faster clicking. It will be a clearer answer to a harder question: who is authorized to turn a recommendation into spend?
Sources verified October 10, 2026: TikTok Newsroom, October 5, 2026; Amazon Ads DVA+, September 29, 2026; IAB Tech Lab AAMP 3.0, September 22, 2026; IAB Tech Lab Buyer Agent documentation; and the NIST AI RMF. Platform announcements establish their own product scope and plans, not universal adoption. The five-level stack, charter and cost model are ONCE analysis.