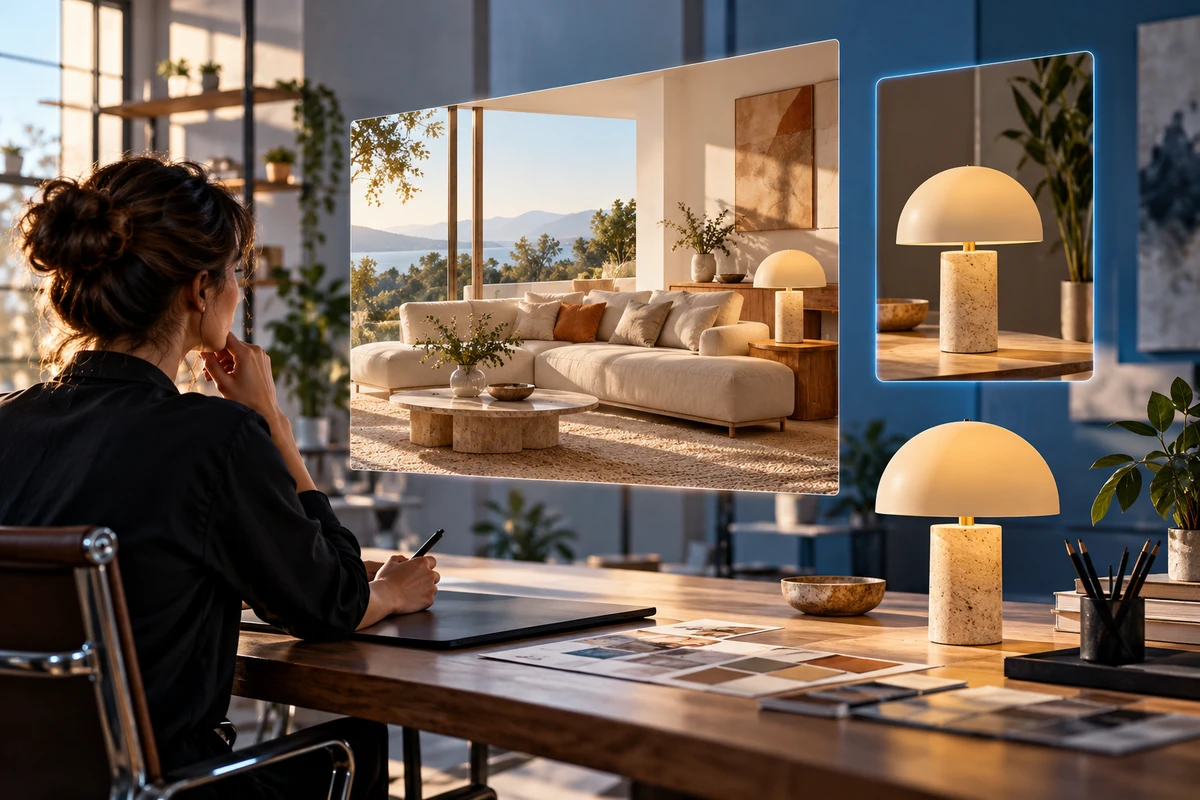
Imagine a user generating a reference image for a warm, timber-lined living room. A visual ad for a lamp appears nearby. That ad is not meeting someone who is passively scrolling. The person is already imagining a space, comparing styles and deciding what could belong in their life. This is more than another image placement. Product creative is entering the moment when a customer is actively constructing a scene.
On October 5, 2026, OpenAI announced a new visual ad format for ChatGPT. The initial test is planned for later in October in the United States, with a starting group of advertisers, and will first appear during image generation for Free and Go users. OpenAI says ads will be clearly labeled, remain separate from the image being created and will not influence ChatGPT's answers. That confirms a test and its initial setting. It does not yet establish universal access, detailed asset specifications or replacement of search, social and retail media.
A beautiful image is not enough; it must help make a decision
A feed ad first competes for attention and then for a click. A visual ad beside image generation behaves more like a useful reference. It needs to show how a product could be used, where it fits and which kind of life it supports—without letting the imagined environment rewrite the product.
Generic lifestyle imagery often provides mood without an answer. A sofa in a beautiful room does not reveal scale. A coffee machine beside morning light and pastries does not show clearance or workflow. A power station at a campsite does not prove the capacity implied by the scene. AI-native visual advertising needs to hold imagination and verification in the same frame.
The ONCE Decision-Scene Stack
Instead of ordering a number of images, assign one buyer question to each decision scene. Every scene contains four layers. If one is missing, the image may look persuasive while remaining unsafe or unusable.
| Layer | Question | Production input | Typical failure |
|---|---|---|---|
| Product truth | What exactly is it? | Accurate shape, scale, material, color, labels, ports and operating states | Invented structure, color drift or rewritten controls |
| Use context | Where, by whom and how is it used? | Spatial scale, human interaction, light, contact and limitations | Wrong grip, exaggerated scale or unsafe use |
| Decision information | What does this scene help someone decide? | One visible answer about fit, setup, cleaning, storage or wear | Several benefits compressed into decorative mood |
| Governance mapping | Where may it run? | Source, generation method, rights, approved claim, destination, market and expiry | Creative and destination make different promises |
The stack turns “make it look premium” into an auditable task. A desk-lamp scene should specify which material and dimensions cannot change, which confirmed lighting ranges may be represented, which decision the image answers, and which product-page version it supports. A generative system may vary the desk, wall and styling. It should not redesign the lamp or imply performance the product cannot deliver.
Build a product-truth pack before expanding scenes
The most valuable additional photography is often not another background. It is a product-truth pack that constrains every background variation. Capture front, side, rear, three-quarter, top and key-interface views; controlled material and color references; open, closed, installed, connected or worn states; scale references; packaging and accessories; and the copy, markings and safety details that must remain unchanged.
This is more demanding than a listing packshot. The truth pack must support generation, compositing, 3D and later video extensions. Google's Product Studio documentation describes its generative features as experimental, notes that unexpected images can occur and identifies limitations for some subjects, including hands, wall art and light fixtures. Adobe's 3D digital-twin workflow shows another route: establish controlled geometry and materials first, then place the product inside generated environments. Both reinforce the same production judgment: environments can become inexpensive variables, but product accuracy remains its own asset.
If a brand already has clean, consistent multi-angle source photography, it can begin by reusing it. If the only source is one compressed marketplace image, a focused truth-pack shoot is usually a safer first investment than using that image as the source for every scenario.
Choose among three production routes
Photograph the product; generate the environment
This works well for stable, opaque products with limited human contact, including selected packaged goods, small appliances and desk devices. Photograph the product and operating states accurately, then generate seasonal, spatial and stylistic variation. Review edges, scale, labels, light direction and destination consistency.
Photograph the interaction; generate the extension
Use this route when hands, wear, load, installation or material deformation affect understanding. Capture the human-product relationship in camera and restrict generation to distant scenery, background or modest expansion. This reduces impossible grips, floating contact and false physics.
Use controlled 3D or a full authored shoot
Choose this for reflective or transparent products, complex assemblies, color-critical finishes, or products that will need many angles and animations. A controlled digital twin or comprehensive capture costs more up front but can reduce repeated repair of the product across many scenes. Regulated claims, safety-critical use and flagship launches should retain a higher level of authored production and human review regardless of how flexible the environment becomes.
Native does not mean imitating ChatGPT
OpenAI's current ad policies require ads to remain distinguishable from the ChatGPT product experience and prohibit interface, functionality or voice imitation that could make an ad appear to be part of the product. The policies also require creative, media and landing pages to remain consistent end to end. Relevance to the user's task is what should make an ad feel native—not fake chat bubbles, copied interface elements or an artificial assistant voice.
The announced separation between the ad and the user's generated image matters too. It does not mean the advertised product will automatically enter the generated result. Our inference is narrower: adjacency to an active visual task raises the value of contextual relevance and product clarity. Matching mechanics, bidding and detailed creative specifications still require further platform disclosure.
Compare proposals with cost per qualified decision scene
A proposal may deliver 30 attractive variations, while 12 alter product structure and eight no longer match the destination. Counting images overstates production capacity. ONCE uses a different denominator:
Cost per qualified decision scene = (truth-pack capture + scene generation or build + human review + destination QA) ÷ scenes passing all four checks
The four checks are product accuracy, contextual plausibility, compliant claims and rights, and destination consistency. The model assumes no industry average and does not treat generation attempts as output. Only a scene that can be deployed, answers one buyer question and preserves product truth belongs in the denominator.
Start with a small scene library, not a channel-wide reshoot
OpenAI's announcement still describes an early U.S. test. For cross-border brands without access, the practical move is not a full channel budget. Start with three recurring buyer questions: how the product fits into a space, how it is used, and how its most important difference becomes visible. For each question, prepare one truth pack, one authored reference image, two or three constrained scene variants and the matching destination.
Add five fields to the next production brief: buyer question, product elements that must remain true, environmental elements that may vary, implications that must never appear, and destination plus owner. If those fields are unclear, generating more imagery simply scales uncertainty. Once they are explicit, photography, AI and 3D can each be used where they create the most value.
For ONCE, the long-term opportunity is not another ad size. It is the move from making individual images to managing product truth, scene variables and decision purpose as a reusable content system. The durable asset is not one beautiful picture. It is a production rule set that knows what may change and what must never change.
Primary sources: OpenAI, “Building advertising for the way people use AI” (October 5, 2026); OpenAI Ad policies (updated September 10, 2026); OpenAI Ads, “More ways to measure ChatGPT Ads” (October 5, 2026); Google Merchant Center Product Studio and Adobe Firefly 3D digital-twin documentation, accessed October 8, 2026. The Decision-Scene Stack, production routes and cost model are ONCE analysis, not platform guidance.