Imagine an international brand sourcing desk lamps from China. One campaign route exists as a written script. Another has become a polished AI preview with acting, a score and attractive product shots. Two prediction reports arrive, and someone proposes choosing the higher number before commissioning production.
First establish what those numbers can compare. The decision may be about the creative route, while the submissions also differ in medium, execution and measurement. A tidy ranking can hide those differences rather than resolve them.
One dashboard does not establish a common scale
Kantar Marketplace Support’s LINK AI dashboard documentation, modified September 17, 2026, says LINK+ and LINK AI results can be accessed together but retain different libraries. Its dashboard deliverables do not directly compare AI and survey data. We checked the guidance on October 17.
That is a stated limit of this product, not a universal claim that model predictions and human research can never be related. A proposed cross-method comparison needs its own explanation of metrics, populations, reference basis and validation. A buyer should not create that relationship by subtracting two displayed numbers.
What is LINK AI?, modified September 16, describes predictions without recruiting a consumer sample for the current evaluation. Video analysis uses visual and audio features; script analysis works from the concepts expressed in text. The documented script outputs are Power and Short Term Sales Likelihood—not observed purchases or a guarantee for a particular campaign.
Its input-format page, modified September 21, specifies a short script summary of one paragraph and 90–150 words, or a long version of two paragraphs and 200–300 words. A constrained summary is not the entire film a director imagines. Confirm how the intended language and submission format are handled rather than assuming every production detail reaches the assessment.
Choose the question before buying the level of finish
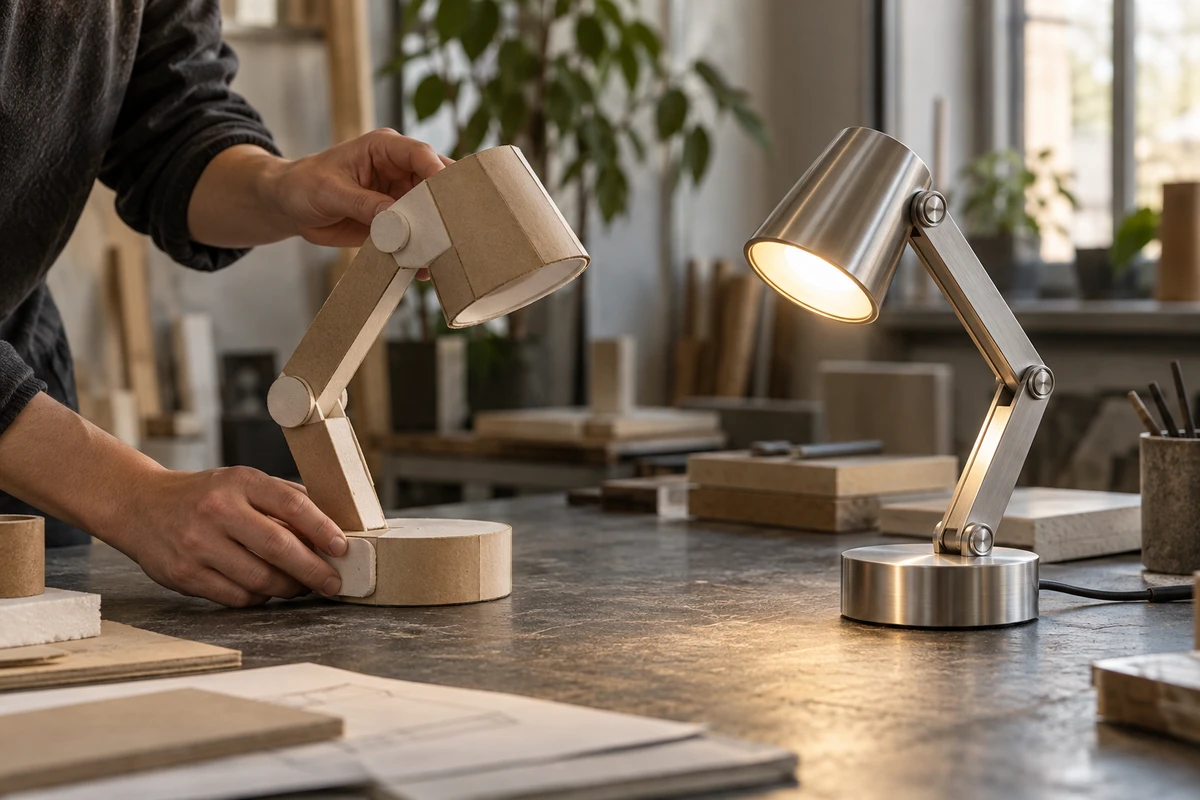
To compare “reading at night” with “light that travels,” bring the lamp concepts to a reasonably comparable expression stage. Hold the agreed product, market, central claim and viewing context steady. Preserve the different story actions: those are the creative alternatives, not errors to standardize away.
Both summaries should explain the person, problem, product contribution and ending clearly. Do not give one a complete functional explanation while reducing the other to a mood line. Comparable preparation means avoiding obvious presentation advantages, not making different ideas identical.
If the decision concerns whether a pause is funny or an unfolding action is understandable, text alone may not answer it. Commission material that expresses the relevant timing, action or sound relationship and use an appropriate evaluation approach. Kantar’s LINK+ media-type guidance, modified September 11, lists early concepts, scripts, mood films, storyboards and ads at different completion stages. Accepting each format does not make each answer the same question.
There is a production market for this preparation. Animatic Media’s Boardomatics page distinguishes timed, voiced illustrated sequences from previews with character movement and photoreal treatments. We use that service distinction, not its turnaround, credentials or testing-success claims. The useful procurement lesson is to buy the fidelity a decision needs—not automatically the most finished-looking treatment.
In the hypothetical lamp project, provide understandable movement in both routes if unfolding is what buyers need to evaluate. If only one idea depends on a specific performance, identify that uncertainty explicitly. Adding persuasive music and polish is not a neutral way to remove it.
ONCE’s Comparison Eligibility Card
This proposed project record is a preparation method, not a testing product or an accuracy claim.
| Before ranking, establish | What the record needs |
|---|---|
| The decision | Are you choosing a route, diagnosing an action or reviewing a finished execution? Do not invent one overall winner across different tasks. |
| The actual input | Version, language, duration, completion stage and anything not yet represented. Do not attribute every difference to the idea. |
| The measurement | Method, model or research version, market or sample definition, exposure context and metric meaning. Mark unknowns as unknown. |
| The comparison basis | Are scale and reference compatible, and does the provider support this comparison? If not, explain results alongside each other without ranking them. |
The card leads to three practical choices. Use a supported within-scope comparison; prepare comparable materials and repeat the specific comparison under one agreed approach; or retain separate diagnoses because the stages answer different questions.
An early-summary prediction and later finished-film feedback can both inform development. They should not automatically become a rising “creative performance” line. Acting, editing, sound and possibly the research method have changed. The numerical difference does not isolate the contribution of any one improvement.
Retesting also has limits. Keeping the original material and exact inputs and outputs helps trace changes. Running one ad through two tools does not establish interchangeable scales or a conversion to sales. If a business needs that inference, an appropriately qualified research team must design the validation rather than the production partner improvising it in a presentation.
Commission decision preparation, not an unexplained score
Separate concept development, test-material production, research execution and interpretation in the scope. A production company may own only the first two. Identify who conducts the research, what result data can be retained and what uses its terms permit. Making an animatic is not the same as completing consumer validation.
For a team working across an overseas brand and Chinese production partners, this also clarifies approval. Agree what each candidate must express before commissioning a polished preview. When findings arrive, preserve the exact submitted version and the decision it informed, including a decision to do more work rather than declare a winner.
For ONCE, repeatable preparation and version-linked learning are a service direction to investigate, not a proprietary prediction system we claim to have built. Client permission, confidentiality, asset rights, research-data licensing and retention periods govern what can be accumulated. A project archive does not automatically become a reusable training dataset.
Any margin or repeat-business benefit would need operating evidence. A useful first scope is concrete: which candidates, which materials, which decision and which interpretation responsibility. That is a clearer starting point for creative video production with ONCE than an undefined promise of “AI testing included.”
Scores can support a choice once the buyer knows what expression was assessed, what question was answered and which comparisons are justified.
Source scope: the four Kantar support documents carry September 11, 16, 17 and 21, 2026 modification dates. The Animatic Media service page has no single stated publication date. All were checked October 17, 2026; they are current documentation, not evidence of a launch that day. No ONCE test, supplier-accuracy validation or campaign outcome is claimed here.