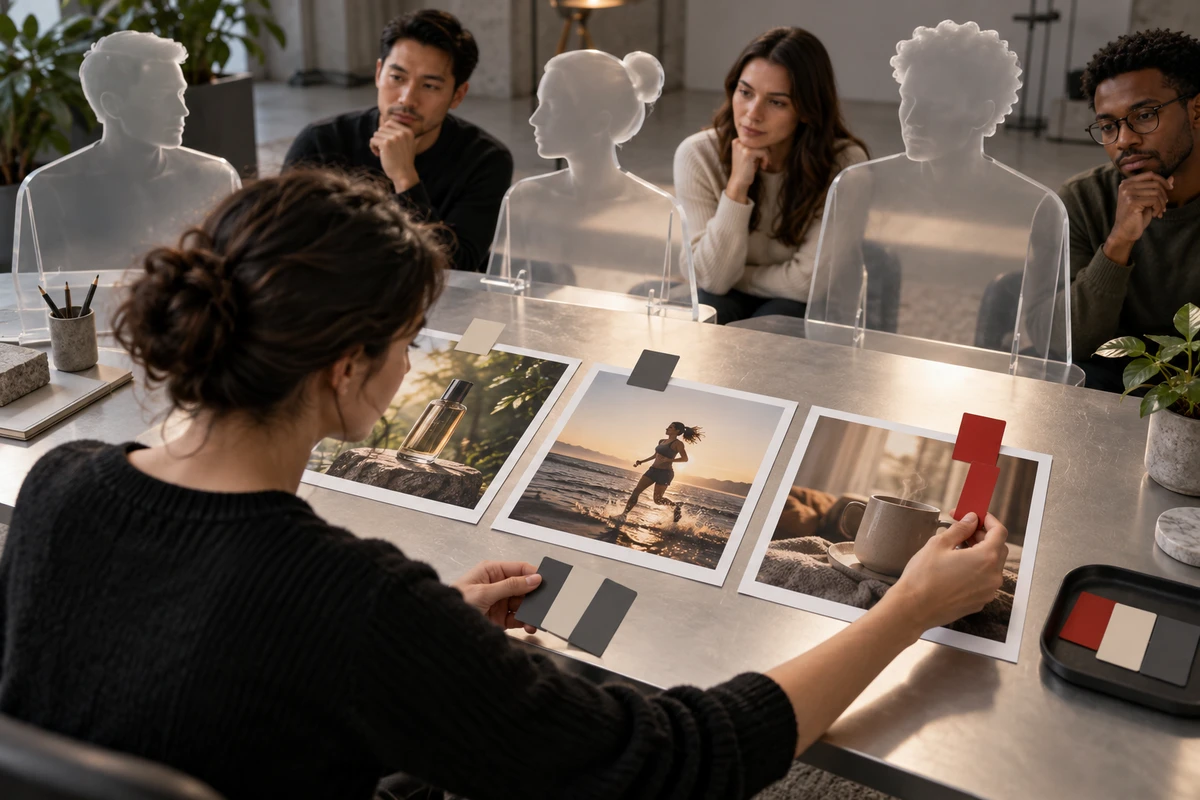
Creative teams can now put scripts, storyboards, stills and rough cuts in front of a synthetic audience before a shoot. The system can compare clarity, relevance and brand fit, then surface likely objections. For brands operating across markets and platforms, the temptation is obvious: if simulated respondents can pick a winner, why recruit people or fund another live test?
That question combines three different jobs. Synthetic audiences are useful for reducing the number of options. Human research is useful for finding cultural and emotional errors a model may miss. Only live exposure can show behavior. Treating all three as one “AI score” may reduce research spend while increasing reshoot and media waste.
The capability is real; equivalence is not proven
Adobe’s Brand Intelligence Simulate documentation, updated June 22, 2026, describes a standard workflow in which teams can upload up to five assets, select audience segments and evaluation metrics, then review scores, interview transcripts and recommendations. Adobe also positions the tool across the development cycle, from early concepts and messaging to rough cuts and finished creative. The product documentation explains the full simulation workflow.
That establishes a production capability. It does not establish that synthetic responses equal fresh human evidence. ESOMAR’s 2026 glossary defines a synthetic sample as model-generated cases that remain distinct from newly recruited participants; source data, generation method, validation, uncertainty and synthetic status should be documented.
The Market Research Society’s 2025 paper, “Our Take: The Right Way to Use Synthetic Data”, calls creative and ad testing a strong use case only when real consumer feedback remains alongside it. It specifically flags emotional nuance and cultural misalignment as risks. Synthetic audiences can become an early filter, but they should not inherit final approval authority.
The ONCE three-layer testing ladder
Layer 1: simulation should eliminate weak options
Before full production, turn three to five concepts into comparable storyboards, stills or low-cost animatics. Keep information density similar and ask operational questions:
- Can the audience identify the product and problem quickly?
- Is the central claim being mistaken for a different category promise?
- Which execution triggers doubt or rejection?
- Do responses diverge sharply across markets or segments?
The output should be “keep two, reject one, add evidence to one,” not “declare a winner.” Save the model version, audience definition, input asset and metric design so the result can be interpreted later.
Layer 2: humans should find what the model missed
The human sample can be smaller after screening, but it must include people who realistically buy or use the product. Do not repeat a generic preference question. Probe language, culture, context and trust. A gesture that signals convenience in the United States may read as carelessness in Germany. A beauty device’s feel and noise cannot be inferred from pictures alone. An industrial buyer may not accept a performance claim merely because a synthetic persona found it clear.
High-risk categories, emerging categories, culturally specific ideas, sensory products and regulated claims should not stop at the simulation layer. Models are usually better at reproducing known patterns than noticing a new dissenting view.
Layer 3: live tests should validate behavior
Interview answers are not completion, click, add-to-cart or sales behavior. YouTube’s 2026 Studio update introduced video A/B testing for up to three cuts to compare which holds attention better. TikTok’s October 2026 Smart+ Creative Selection update brings owned, AI-generated and creator assets into one approval and activation workflow. These systems can expose real behavior, but their automated selection does not explain the causal reason.
Keep a stable control, a clear primary variable and comparable audience and spend. Feed the result back into the next production brief. ONCE’s earlier guide to two-stage TikTok Shop creative testing is useful here: compare genuinely different routes first, then control hooks, pacing and execution variables.
Budget for misclassification, not just research fees
A useful planning equation is:
Total testing cost = simulation + human validation + live experiment + expected rework after a wrong decision.
Synthetic audiences create value by reducing the number of concepts entering expensive stages—not by making every later stage disappear. If a shoot requires sets, talent, prototypes and multiple market versions, cutting five directions to two before deep development can be valuable. If the system eliminates the one direction that would unlock the market, the loss can exceed the entire research budget.
Use one escalation rule: when the potential loss from a false rejection or false approval is greater than the cost of added human or live validation, the process cannot stop at simulation. This is more useful in procurement than asking for the largest possible synthetic sample.
Production deliverables need to change
Production companies traditionally create testable assets after a script is approved. A synthetic-audience workflow moves that work upstream. The pre-production package should include comparable concept cards, one clearly labeled variable per route, storyboards or rough animatics, and a list of conclusions that still require people or live media.
For ONCE, the commercial opportunity is not to surrender taste to a model. It is to turn pre-shoot debate into traceable hypotheses. A brand can require five records from its partner: audience definition, asset version, evaluation question, rejection rationale and next validation method. Without them, a polished AI insight report is difficult to translate into a shot list.
The decision is straightforward. Use synthetic audiences as a filter at the top of the funnel, not as a gate. Let simulation expose confusing ideas quickly, let people catch cultural and emotional error, and let the market show whether audiences act.
Sources
- Adobe Help Center, “Create simulated brand analysis,” updated June 22, 2026
- Adobe, “Synthetic audience testing in Adobe Brand Intelligence,” 2026
- ESOMAR Glossary, Synthetic Sample and Synthetic Respondent
- Market Research Society, “Our Take: The Right Way to Use Synthetic Data,” 2025
- Ipsos, “AI Ads Are Good Enough — And That’s the Problem,” May 18, 2026
- YouTube, “Made On YouTube 2026”
- TikTok Newsroom, “AI-Powered Updates for Advertisers,” October 6, 2026