A folder of a brand’s best-looking images is not automatically a useful training dataset. A production-ready set has a different job: it must help a model distinguish what should remain constant from what is allowed to change.
Adobe’s Firefly documentation, updated on October 13, 2026, says a custom model can be trained with 10–30 representative JPG or PNG images. It also asks teams to include variations they want the model to learn—such as different perspectives, compositions and backgrounds—then review the generated captions and tags. Before training, the user must confirm that they have the necessary rights to the images. Those are Adobe’s current product requirements, not a universal industry standard, and they do not guarantee that any ten uploads will produce a reliable brand model.
The strategic implication is more useful than the number. A product shoot can now serve two outputs: campaign assets for today and structured visual coverage for future generation. Those outputs should not be selected in the same way. Campaign editing seeks the strongest frame. Training-set production deliberately shows what remains true across different frames.
Define the training task before booking the shoot
A custom model is most defensible when the same product, character or visual system will appear repeatedly; the team expects meaningful volume across markets or channels; and the brand can identify the attributes the model must not rewrite.
For a one-off campaign, an imminent packaging change, or work that requires exact regulatory text and millimetre-level product fidelity, controlled photography and compositing may still be the better investment. A model that looks on-brand is not necessarily accurate about port counts, labels, safety actions or performance claims.
Start with one task statement: is the model meant to reproduce a subject, a recurring character, or a style? Adobe’s current workflow distinguishes style and subject models. For a specific person, character or still-life object, it also uses a stable name and Concept ID in captions and prompts. Mixing those goals without a hierarchy produces a confused shot list and an equally confused acceptance test.
The ONCE COVER framework for training-image production
We recommend adding five requirements to the production brief. COVER is not an Adobe feature. It is a vendor-neutral acceptance method a brand can retain even if its model or platform changes.
C — Constants: show what must not drift
List the product silhouette, proportions, structural details, material behaviour, colour, texture, character face and wardrobe that must remain stable. Each constant should appear under more than one angle or lighting condition, so the model is less likely to mistake a reflection, background colour or one camera position for the identity itself.
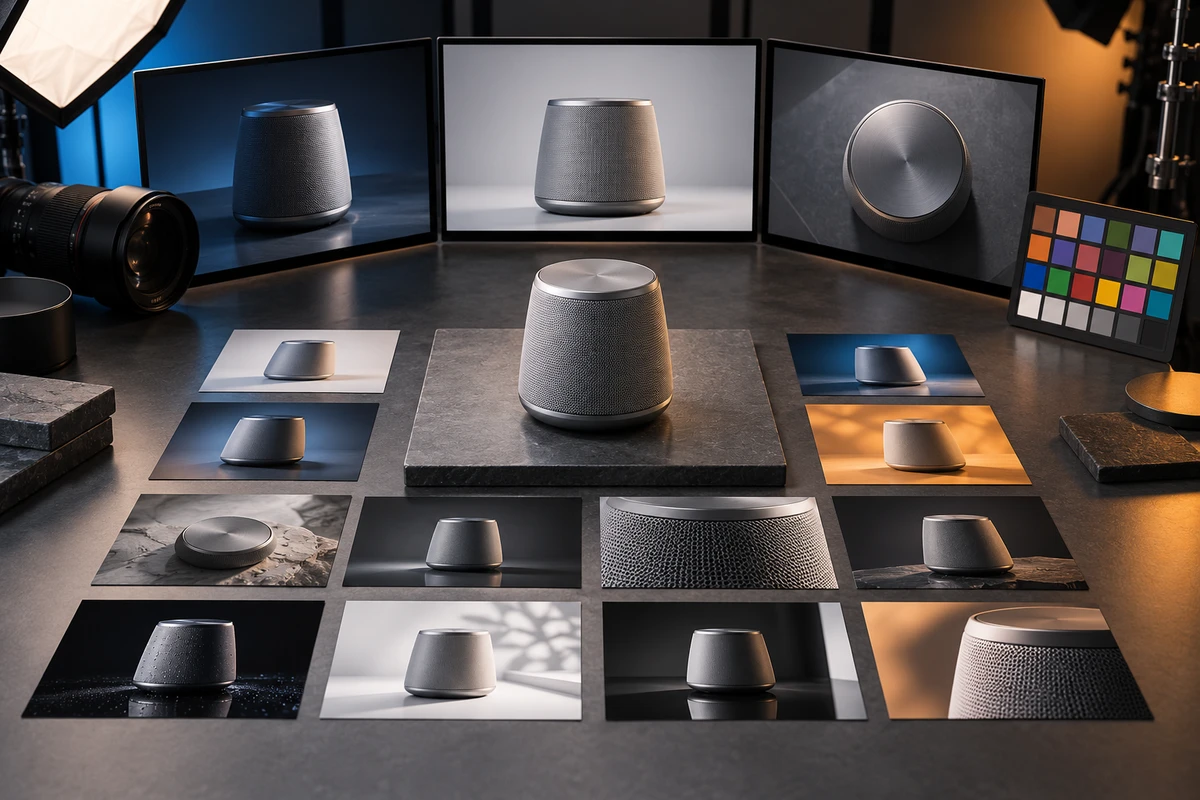
A hero image of a silver speaker can communicate attitude. It cannot explain rear ports, top controls, grille texture and side depth. A training shoot must add those observation points while preserving trustworthy colour and scale references.
O — Options: design the useful variation
Variation should be intentional, not maximal. List the angles, framing, composition, background, lighting, environments and prop relationships the future workflow actually needs, then assign minimum coverage to each. A model intended only for e-commerce still life does not need a dataset dominated by people. A model for global social content may need broader context, aspect-ratio headroom and human interaction.
This is different from “shoot more options.” Every selected image should introduce a known variable. Near-identical burst frames should not be counted as separate evidence.
V — Validation: keep acceptance prompts outside the training set
Do not train on every image and then use those same images to prove success. Hold back references and agree on fixed prompts before training—for example, three new backgrounds, two unseen angles and one interaction scene in which the product must retain its structure, material and colour.
Review at least three dimensions: identity consistency, controllable variation and factual error. A model that only reproduces training compositions has not generalized. A model that creates attractive settings but keeps changing a connector or label is not ready for commercial production.
E — Entitlements: verify that “licensed” includes training
Ordinary campaign usage does not automatically include model-training rights. Talent releases, photography ownership, stock licences, fonts, prop artwork, partner products and outsourced design need an explicit answer: may they be used for training, by whom, in which account or project, and how is access withdrawn when the engagement ends?
Adobe requires the user to confirm that they have the necessary permissions before training. Its management documentation also says deleting a custom model removes the model along with its training assets and captions, while access to a project can carry access to models stored in it. Those are specific properties of Adobe’s current workflow. Operationally, they are also a reason not to leave the only copy of a brand’s training set inside a supplier-controlled account.
R — Records: deliver captions, tags and versions with the files
Each image should carry at least an asset_id, subject or
SKU, view, lighting, background, capture date, rights status, permitted
use, checksum and approver. Machine-generated captions and tags require
human review, especially for colour, material, structure and subject
names.
This connects to ONCE’s work on AI-assisted product and campaign production: a product truth layer answers “what is the product?” A training coverage layer answers “what variation must the model see to reproduce it reliably?” The two should share identifiers rather than become parallel folders.
Build the shot list around coverage units, not image count
A practical shot plan is a constants-by-variables matrix. Rows contain the attributes that must remain stable. Columns contain allowed changes. Every capture should answer one question: which new observation point does this image add, or which constant does it verify under a different condition?
The team does not need to photograph every theoretical combination. Start with high-risk structure and high-frequency generation scenarios, run a first training cycle, then shoot the missing coverage. For SKUs that share geometry but differ in colour, decide whether colour generation is acceptable. If colour drift creates returns or compliance risk, treat each colour as a controlled subject instead of assuming the model can swap it accurately.
Completion should not read “20 images delivered.” A better acceptance line is: all constants have clear references; planned variables meet minimum coverage; near-duplicates are removed; captions and tags are reviewed; training and access rights are confirmed; and the fixed validation set is complete with failure types recorded.
Price the usable training unit, not the shutter count
Training-image cost includes more than studio time. A useful internal comparison is:
Cost per usable training unit = (coverage design + capture + curation + caption/tag review + rights clearance + validation + remediation) ÷ units that pass identity, factual, rights and validation checks
A training unit is not simply a file. Twenty near-identical front views may add one unit of coverage; one carefully made rear view that resolves ports and structure may add far more value.
Teams can also track a first-pass validation rate: outputs that pass identity, factual and brand review on the first generation, divided by all outputs from the fixed acceptance prompts. This is not a sales metric and should not be used to compare ROAS across models. It answers a narrower procurement question: did the dataset reduce rework?
Who should change the brief now—and who should wait
Brands with a persistent character, stable packaging, multiple markets and recurring content demand should add training coverage to the next shoot. The supplier’s handoff should include coverage design, source files, rights status, reviewed captions and tags, a validation set and targeted reshoot recommendations—not just a folder of polished selects.
For short campaigns, fast-changing products or high-fact-risk categories, prioritize accurate source photography and editable masters. A small training pilot can test whether the model actually reduces downstream version cost before the brand funds a larger dataset.
Adobe’s releases show that one major creative platform is turning custom models, asset analysis, captions, tags and project access into an operational workflow. They do not prove that brands can now shoot less and generate forever. The more durable move is to upgrade photography from finished-image supply to training-coverage supply—so every image has a reason to exist, a known lesson for the model and a right the brand can continue to exercise.
Source scope
Primary sources reviewed for this article include Adobe Help Center’s Create and train custom models (updated October 13, 2026), View, edit, and manage custom models (updated September 21, 2026), and Adobe’s June 18, 2026 announcement of Firefly Elements and Projects. These sources establish Adobe’s current requirements and beta workflow only. The COVER framework, coverage matrix, cost logic and procurement recommendations are ONCE analysis.