On October 6, 2026, Shopify described a shopping request that would have looked absurd in a traditional keyword report: a gift for an eight-year-old who loves sharks but already owns almost every obvious shark-themed item. The useful signals are not a brand name or a neat category. They are age, interest, ownership history, novelty and gifting context.
That example is Shopify explaining its own commerce infrastructure, not proof that every retailer has already moved to the same model. But current OpenAI documentation shows the same structural pressure from another direction. ChatGPT shopping results are selected for relevance to the user’s query and context. OpenAI’s direct product-feed guidance asks merchants to keep identifiers, descriptions, prices, inventory, media and fulfillment options refreshed.
Together, these first-party sources establish a narrower—and more useful—fact: commerce systems need to understand a product before they can judge whether it fits a specific request. For brands, that changes what a product-video brief should buy.
A complete feed can still leave the buying question unanswered
Structured product data is good at stating the SKU, color, size, inventory and price. It may still fail to answer questions such as:
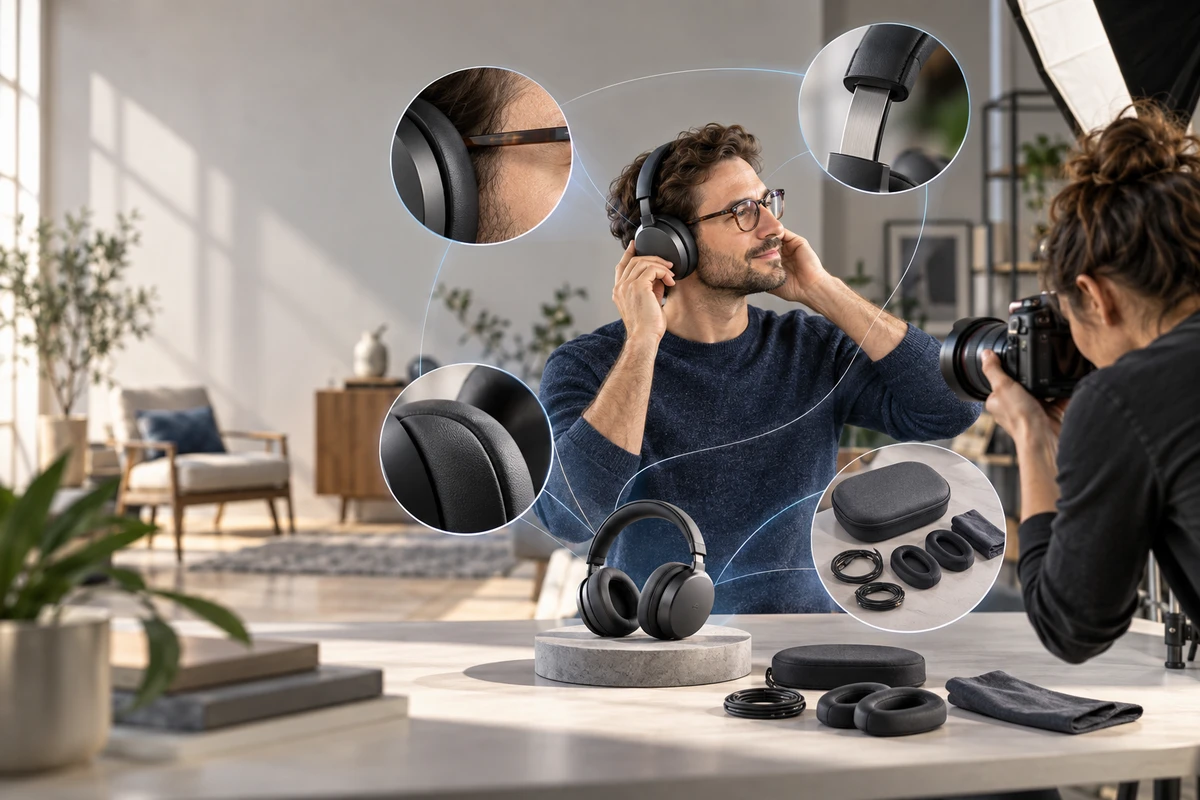
- Will these headphones press against thick glasses arms?
- How much floor space does this product occupy after folding?
- Can a user operate it with wet hands?
- Which wall types can support the supplied mount?
- Does the gift box include the adapter shown in the video?
These are constraint-led questions. Their answers often cross the product, accessories, a human action and the use environment. A wrong answer can become a return, a poor review or an avoidable support ticket.
This is why a brand should not simply attach “a video” to a complete product feed. It needs observable scenes that support the most important fit decisions, with every scene linked to the product fact and version it represents. Our earlier piece on responsive commerce creative argued that brands should commission recombinable components rather than one fixed banner set. Agentic discovery adds another requirement: each useful component should answer a defined buying question, not merely occupy a placement.
The ONCE Constraint-to-Scene Matrix
Before writing the storyboard, build a six-column matrix for each priority SKU:
- Buyer constraint: who the product is for, the environment, and the device or habit it must work with.
- Decidable answer: suitable, unsuitable or suitable only under a named condition.
- Product fact: the measurable specification, compatibility rule, material, bundle content or fulfillment promise behind the answer.
- Proof scene: an action, comparison, scale reference or installation step that makes the answer visible.
- Version anchor: SKU, accessory, packaging, firmware, market and effective date.
- Publishing limit: claims that cannot be made yet and exceptions that require engineering, legal or support review.
Consider the claim “carry-on friendly.” A generic airport walk does not answer the constraint. Which airline rule applies? Do wheels and handles count in the dimensions? Is the filmed sample the same SKU now on sale? If requirements vary by carrier and route, the responsible scene shows the measurement method and exact dimensions instead of promising universal acceptance.
“Comfortable with glasses” has the same problem. A smiling model is weak evidence. A useful asset set can show the contact point between the frame arm and ear cup, the adjustment range, the pressure-distribution structure and normal head movement. It should also preserve the limitation that frame thickness and head shape change the experience.
The goal is not to turn every product video into a laboratory report. It is to make the conditions most likely to change a purchase decision visible, honest and reusable.
Price the work by questions answered, not edits delivered
Cost per cut rewards output volume. A team can create ten mood variations from the same footage without answering one additional question. ONCE therefore recommends a second internal metric:
Cost per answerable buying question = (proof-scene production + claim validation + data binding + localization) ÷ approved independent questions that product data can point to.
A question enters the denominator only when four conditions are met: the answer is explicit; a viewer can see supporting evidence; an accountable product fact or owner backs it; and the asset is tied to the correct SKU and market version.
This is not an industry benchmark and it does not predict conversion on its own. It is a purchasing control. It lets a team compare ten more stylistic edits with five new scenes that resolve high-value fit constraints.
A 14-day pilot is enough to test the operating model
During week one, collect 20 constraint-led questions from customer support, return reasons, site search, reviews and sales conversations. Remove pure price and stock questions. Rank the remainder by purchase impact, current answer gap and harm from a wrong answer. Select the top five, then have product, support and marketing agree on each answer.
During week two, capture only the reusable proof scenes. Give each shot one primary question, but protect enough clean framing for vertical and horizontal use. When publishing, the product page, feed, captions and scene should express the same answer. If the product fact changes, the matrix identifies which assets must be withdrawn or reviewed.
If a high-frequency question has no stable answer, do not film around the uncertainty. The missing asset may really be a missing specification, accessory policy, packaging rule or fulfillment promise. Content should not disguise an unresolved product-operations decision.
The procurement decision that changes
For a brand, the supplier question is no longer only “How many videos can you deliver?” It is also: “Can your team translate buyer constraints into reviewable scenes and maintain the SKU and market version behind every claim?”
For a production company, the defensible new service is not simply generating more variants with AI. It is a decision-evidence system spanning question discovery, fact validation, proof-scene design and product-data binding.
For ONCE, the compounding asset is the relationship table: which scene answers which question, for which SKU, in which market, and until what changes. That table lets trusted footage serve product pages, ads, sales conversations and shopping agents without pretending that one generic hero film can answer every buyer.
Sources and limits
The current platform facts in this article come from Shopify’s October 6, 2026 article “Welcome to the first holiday season of the agentic era”, Shopify’s March 24, 2026 announcement “Millions of merchants can sell in AI chats”, OpenAI’s updated help article “Shopping with ChatGPT Search”, and OpenAI’s Agentic Commerce key concepts.
Those sources establish what the named companies publish about their present systems. They do not prove that all shopping platforms rank products the same way. The Constraint-to-Scene Matrix and cost formula are ONCE operating methods, not platform ranking factors or industry standards.